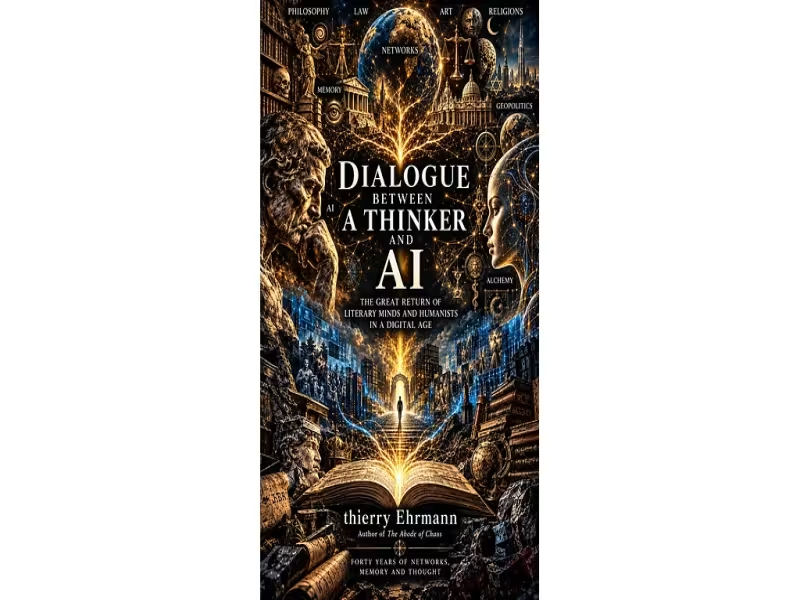
Paris – September 20, 2026 -- A newly published book, "Dialogue Between a Thinker and AI," has become the test object for a comparative experiment feeding identical text to five major artificial intelligence systems: OpenAI/Astra, Perplexity, DeepSeek, Google Gemini and xAI/Grok. The French and English print editions are now available, but the project's core output is a public meta-reading exercise designed to expose how differently large language models interpret the same source material.
Five AI systems receive an identical corpus for independent analysis
Each model is given the full text of the book, generated originally through hundreds of hours of dialogue between a human thinker and AI. Researchers behind the project state the goal is not to rank the models but to document where their readings converge, diverge, or miss entirely.Models are then set to critique one another's interpretations
After each AI produces its own reading, the outputs are cross-fed: Gemini reviews Grok's analysis, DeepSeek responds to critique from OpenAI/Astra, and so on. A third system is then used to analyze the resulting confrontation between AI-generated critiques, turning commentary into new corpus material for further analysis."We didn't ask AI to judge the book. We asked AIs to read it — and then to read one another," the project states.
Experiment targets concept selection and interpretive blind spots across models
Specific comparison points include which concepts each model identifies as central, which passages it links together, and where its interpretation departs from the others. The organizers frame the divergences themselves as the primary data output, arguing that gaps between AI readings reveal more about model architecture than any single analysis would.Human oversight remains central to the comparative framework
The project explicitly does not delegate final judgment to the machines. Humans are tasked with comparing, contextualizing and deciding among the AI-generated readings, while the systems themselves only produce raw interpretive output for that human review.The meta-reading corpus and methodology are published alongside the book at the project's dedicated online platform, positioning the work simultaneously as a literary publication, a research corpus, and an open benchmark for AI interpretive behavior.