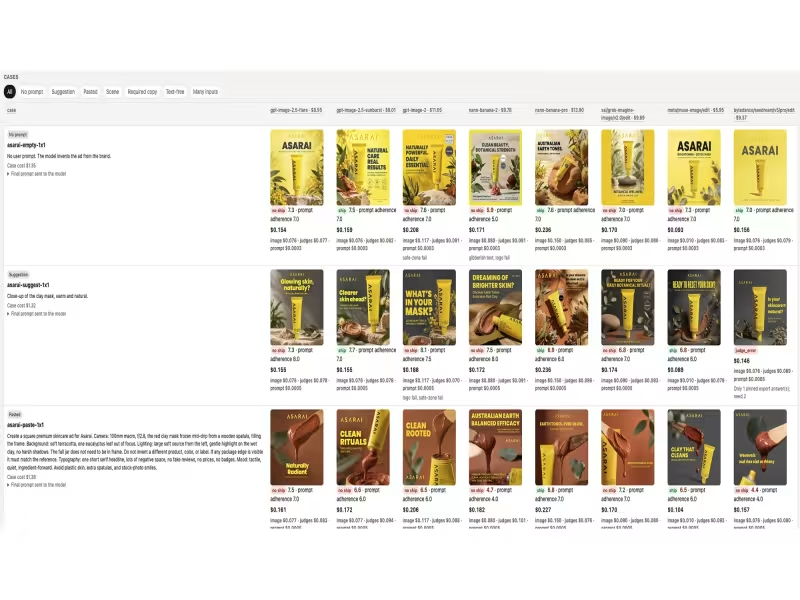
San Francisco – September 25, 2026 -- Omneky has launched TASTE BENCH, an evaluation suite that scores whether AI-generated image and video ads are ready to run without human rework.
GPT Image 2.5 Sunburst leads eight models with a 54.2% ready-to-run rate
In first-attempt tests across eight image models, GPT Image 2.5 Sunburst produced ready-to-run ads 54.2% of the time (32 of 59 briefs), scoring an average quality of 7.38 out of 10. Ready-to-run rates across all eight models ranged from 22.0% to 54.2%, with Omneky's own review step disabled during testing.
The benchmark covers 469 ads generated across four brands and five languages
The current edition of TASTE BENCH spans eight image models, 59 ad briefs, four brands, and five languages -- English, Japanese, Arabic, Hindi, and Spanish. The tests generated 469 ads and produced 1,371 valid blind judge reviews.
A blind panel of AI judges from OpenAI, Anthropic, and Google scores each output
Models receive identical prompts and brand assets, then a blind panel of AI judges scores outputs across eight quality dimensions, including brand fit, typography, and ad effectiveness. Eleven pass/fail checks assess exact copy, correct language, faithful logos and products, safe-zone placement, and fabricated claims or visual artifacts.
An ad counts as "ready to run" only if a majority of judges would approve it as-is
Under the panel's voting rules, an output is classified as ready to run when it passes applicable hard checks and a majority of judges indicate they would run it without edits. Omneky notes the results reflect automated creative judgments only, not campaign conversions or return on ad spend.
Hikari Senju, founder and CEO of Omneky, said the benchmark was built to make judgments about typography, product authenticity, and creative clarity systematic, so the company knows which models to trust with customer ads.
Omneky's AI Growth Agent selects among image and video models from multiple labs for each ad it produces.