AI Infrastructure

TI Debuts 3 GSPS ADC and 800V Controller for AI Data Centers
Image
TI Debuts 3 GSPS ADC and 800V Controller for AI Data Centers

San Jose – October 12, 2026 -- Texas Instruments (Nasdaq: TXN) unveiled the ADC34DSO75, a 3 gigasamples-per-second analog-to-digital converter that it says enables 24/7, low-power, event-based remote monitoring at nanosecond resolution, thousands of times faster than current solutions.

The company debuted the device at the Open Compute Project (OCP) Global Summit alongside two other analog products aimed at AI data center power instability, inadequate real-time monitoring and signal degradation. TI says these problems can lead to costly downtime.

ADC34DSO75 targets nanosecond power-rail glitches that cause downtime

TI says existing monitoring tools often miss nanosecond-level power-rail glitches behind unplanned outages. The ADC34DSO75 combines ultra-high-speed sampling with on-chip digital signal processing in a small form factor to detect and capture transient fault events in real time.
insidepacket Launches AI Access Platform, Starting With Zayo Europe

Image
insidepacket Launches AI Access Platform, Starting With Zayo Europe

Palo Alto – October 12, 2026 -- insidepacket has announced the AI Access Platform, which connects enterprises to GPU and neocloud providers through private network paths that can be activated in minutes. The platform is planned for introduction in Europe, first with Zayo Europe.

Platform comes in two models for GPU clouds and operators

The first model is a dedicated on-ramp that a GPU cloud sells under its own brand. The second is an operator layer that exposes many GPU clouds to the operator's enterprise customers. The underlying NaaS platform has been in production in the US since September 2025 and in Europe since mid 2026.

GMIF2026 Awards Name 18 AI Memory and Storage Leaders

Image
GMIF2026 Awards Name 18 AI Memory and Storage Leaders

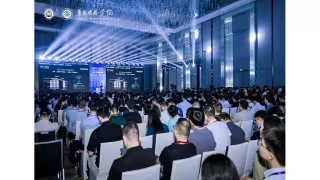
Shenzhen – October 12, 2026 -- The 5th Global Memory Innovation Forum (GMIF2026) has named 18 companies across memory, compute, packaging and testing equipment, test systems and end applications in its first GMIF2026 Annual Awards, led by Samsung Semiconductor, Sandisk, CXMT and Lenovo.

The summit was held at the Renaissance Shenzhen Bay Hotel and co-hosted by the Shenzhen Memory Industry Association and the School of Integrated Circuits at Peking University. Its theme was "The Future Built on AI Memory and Storage," with the token economy as a key lens. Winners were judged on technology innovation, industry contribution, market service and application results.

Foxconn's Kathy Yang Named to Fortune Asia Power List Again

Image
Foxconn's Kathy Yang Named to Fortune Asia Power List Again

Taipei – October 12, 2026 -- Kathy Yang, General Manager of Global Campus Operations and Head of AI Software Business and AI Infrastructure at Hon Hai Technology Group (Foxconn) (TWSE:2317), has been named to Fortune's Most Powerful Women Asia 2026 list for the second consecutive year.

Technology leads the 2026 list with 16 honorees, ahead of banking's 14

Technology is the most represented sector in this year's ranking. Fortune's Asia list Senior Manager Charmian Choo said the sector's prominence reflects its growing influence on Asia's economy, with established leaders and a newer generation both rising.

SWI Group Raises €800M at €6.1B Valuation for AI Compute Push

Image
SWI Group Raises €800M at €6.1B Valuation for AI Compute Push

Amsterdam – October 12, 2026 -- Euronext Amsterdam-listed SWI Group (SWICH) has raised €800 million from institutional investors at a final valuation of €6.1 billion, lifting total equity raised since March 2026 to more than €1 billion.

New share series lift capital base to 558,399,385 ordinary shares

SWICH is issuing the new ordinary shares in several series. The total share capital rises to 558,399,385 ordinary shares after the transaction.

Proceeds fund data center and AI compute build-out in Europe and the US

The company will use the proceeds to develop and scale its data center and AI compute capacity. Spending covers power infrastructure, compute deployments and its development pipeline on both sides of the Atlantic. SWI describes the raise as a step in consolidating its transatlantic digital infrastructure and AI compute platform.

CIQ's RLC Pro AI Adds Kernel 6.18, 10-Minute Local AI Stack

Image
CIQ's RLC Pro AI Adds Kernel 6.18, 10-Minute Local AI Stack

Global – October 12, 2026 -- CIQ's latest RLC Pro AI release lets a developer stand up a working local AI stack in about 10 minutes and adds CIQ Linux Kernel 6.18 for large production environments, according to Brian Dawson, the company's Director of Product Management.

CIQ targets the operating system as the overlooked layer of AI stacks

Dawson argues that organizations pour capital into GPUs, models, frameworks and applications while treating the operating system as an afterthought. "We've moved so fast with AI that the OS has become the forgotten layer," he said.

CIQ: Linux 6.18 Loads AI Model Weights 33.8% Faster

Image
CIQ: Linux 6.18 Loads AI Model Weights 33.8% Faster

Santa Clara – October 12, 2026 -- CIQ says model loading ran 33.8 percent faster on Linux 6.18 than on a kernel frozen at general availability, based on its own benchmarks of the same workload. The company is pitching the result for RLC Pro AI, its Enterprise Linux distribution for GPU infrastructure.

CIQ's argument is that AI hardware and frameworks move faster than the operating system beneath them. NVIDIA advances the hardware, CUDA the toolkit and PyTorch the framework. An enterprise kernel, by design, trails by an average of twelve to eighteen months. RLC Pro AI ships Linux 6.18, the latest production and long-term GPU drivers, and the CUDA toolkit together, validated as one stack.

CIQ Fuzzball 4.2 Lets AI Agents Run HPC Workflows Under Admin Control

Image
CIQ Fuzzball 4.2 Lets AI Agents Run HPC Workflows Under Admin Control

United States – October 12, 2026 -- CIQ's Fuzzball 4.2 allows AI agents to interact with the HPC platform within permissions set by the customer organization, and lets workflows submit and manage other workflows. Research Computing Engineer Wolfgang Resch, who spent roughly a decade supporting researchers at the NIH High Performance Computing facility, says the agent access will lower the barrier to entry for new users and speed development of Fuzzball workflows.

Fuzzball 4.2 adds agent access and workflow-to-workflow submission

Resch sees opportunities to fold Fuzzball into existing agentic workflows and to help administrators investigate cluster issues. Workflows that launch other workflows enable more complex applications and simplify integration with workflow engines such as Nextflow.

Fuzzball v4.3 Ships 11 Preset LLMs for Self-Hosted GPU Serving

Image
Fuzzball v4.3 Ships 11 Preset LLMs for Self-Hosted GPU Serving

Global – – October 12, 2026 -- Fuzzball v4.3 adds a vLLM catalog entry and eleven validated model presets that serve a large language model from a pool of replicas on NVIDIA or AMD GPUs, behind an OpenAI-compatible endpoint.

Eleven presets come with GPU count, context size and vLLM arguments already set

The generic vLLM entry serves a HuggingFace model from a single catalog command. The eleven presets cover GPT-OSS 20B and 120B, Ministral 3 8B and 14B, Qwen3-Coder 30B and Next 80B, Nemotron 3 Nano and Super, Mistral Medium 3.5, Llama 4 Scout and Gemma 4 31B. Each has its GPU fit and serving arguments validated per model.

Users can accept the preset values or override them. In one example, a persistent volume keeps the downloaded checkpoint between starts, and MaxReplicas is raised to eight so the pool can grow under load.

CIQ Fuzzball 4.3 Launches Private LLM Inference in a Few Clicks

Image
CIQ Fuzzball 4.3 Launches Private LLM Inference in a Few Clicks

United States – October 12, 2026 -- CIQ's Fuzzball 4.3 lets users launch large language models for inference in a few clicks, drawing on a catalog of nearly a dozen preconfigured LLMs that can run on an organization's own HPC cluster or in the cloud.

Fuzzball 4.3 removes manual setup for LLM serving

Users pick a model from the workflow catalog and interact with it through a browser or command line client. Fuzzball scales model services up or down with demand and provides a durable endpoint for access.

Earlier versions required more work for any model missing from the catalog. Users had to write a Fuzzfile, determine the model's compute requirements, sometimes by trial and error, and find a way to reach an autoscaled node pool without a single endpoint. Version 4.3 removes most of those steps.